
Last updated September 18, 2026
4 min read
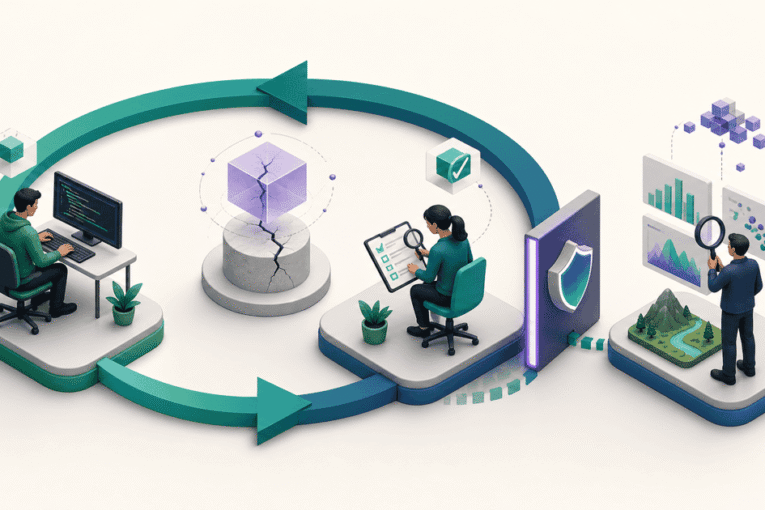
A fictional loop writes a date rule with the wrong timezone, generates tests in the same timezone, and asks a reviewer using the same context to judge it. Three correction turns improve naming and coverage while preserving the core error. This is an explicitly fictional composite, not a customer result.
In this article
Consistency can hide shared error
Internal agreement is not external validity. The worker and test generator can converge on one interpretation, while the evaluator rewards consistency. The loop looks healthy because every artifact tells the same wrong story.
Risk of coding before testing, July 2026 supports the evidence boundary. A recent preprint in a bounded setup that needs replication.
| Item | Inspectable value |
|---|---|
| 1 | 3 correction turns |
| 2 | 1 shared timezone assumption |
| 3 | 2 reviewer error directions |
| 4 | 0 independent behavior examples |
Use the table as a diagnostic, not benchmark data. Replace illustrative entries with repository evidence before changing staffing, policy, or release authority.
Evaluator quality has two failure directions
Code reviewers can falsely accept unsafe code or falsely reject correct code. The 2026 reliability study showed prompt-sensitive trade-offs and that filters shifted them. Track both directions. An evaluator that blocks everything is not safe; it has moved cost into false rejection.
Sequence matters. When an early input is missing, later activity can look complete while a reviewer inherits the unresolved uncertainty.
Independent evidence must enter the loop
Bring in behavior examples written from the approved specification, registry data, schema checks, mutations, specialist findings, and human product decisions. Label whether evidence is deterministic, model-judged, or human. Independence is a property to inspect, not a model count.
Reliability of LLM code reviewers, 2026 provides a second check. Small benchmark functions and prompt-sensitive trade-offs; execution did not prove correctness.
The fix is procedural because a procedure can be rehearsed and audited. A warning without ownership rarely survives a busy release week.
Stop repeated correction without information gain
Stop after repeated failures with no new evidence, specification mismatch, unchanged surviving mutations, budget limits, or sensitive uncertainty. A fourth stylistic rewrite is not correction if the core premise remains untested.
paqad-ai v1.67.0 was the current public release when this article was verified on July 21, 2026. The repository describes local workflows, risk routing, structured state, checks, documentation sync, and audit records. Those are inspectable mechanisms, not independent proof of a business result.
Use the AI workflow audit guide for current-state mapping, compare the evidence bar with production-ready AI code, and read the AI coding consultant guide when outside support is relevant.
Decision rule: Allow another loop turn only when it introduces new evidence or a materially different test of the disputed behavior.
Run the evaluator-independence audit in a 45-minute working review with the product owner, module owner, and final reviewer. Do not turn it into a score. Read the decision rule aloud: Allow another loop turn only when it introduces new evidence or a materially different test of the disputed behavior. Record disagreements, missing evidence, and the person responsible for the next action. Repeat the review after one real feature so the team can compare whether the artifact reduced ambiguity or only added paperwork.
Frequently Asked Questions
What makes evaluator evidence independent?
It comes from a source not derived from the same implementation assumption, such as approved product examples, authoritative schemas, live registries, independent fixtures, or a qualified specialist.
Should the evaluator use another model?
It can, but a different model name is insufficient. Separate context, criteria, role incentives, and evidence matter more than vendor diversity alone.
How many correction turns are safe?
Set a small budget based on risk and cost. More important, require information gain. If another turn adds no new evidence or repeats the same failure, stop and escalate.
What next?
Apply the evaluator-independence audit to one active feature. If the repository cannot produce the required state and evidence, install paqad-ai and test the workflow locally with a named human decision owner.