
TL;DR
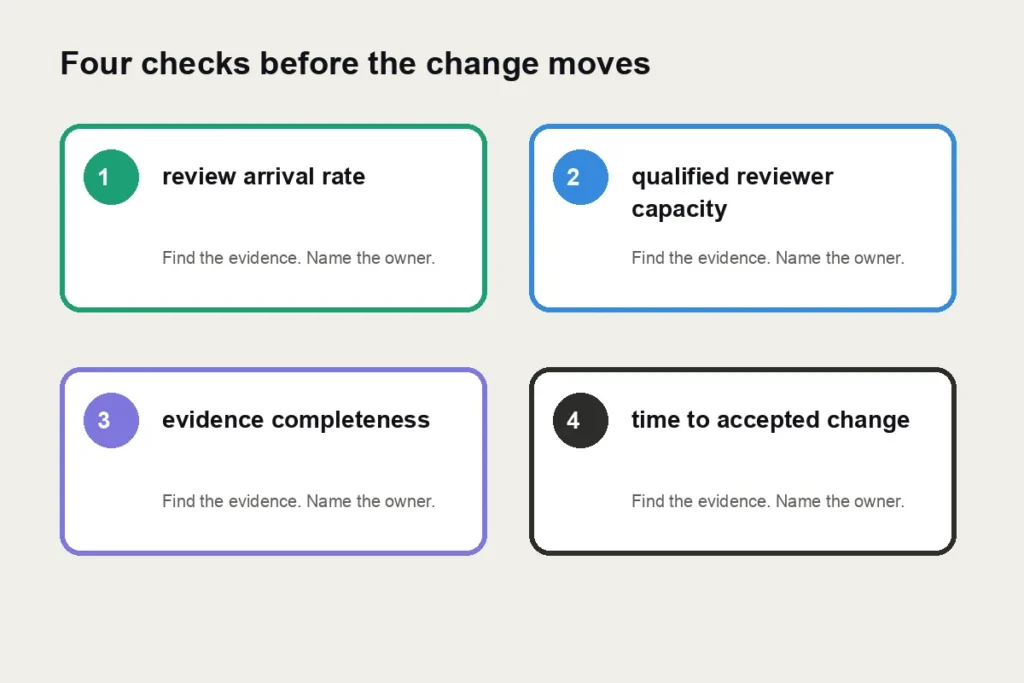
AI coding creates a review bottleneck when generation increases faster than the team’s ability to verify intent, risk, tests, and maintainability. Inspect review arrival rate, qualified reviewer capacity, evidence completeness, and time to accepted change on one recent change. If another qualified reviewer cannot reach the same decision from the stored evidence, pause and repair the earliest missing handoff before increasing automation or output. The goal is dependable delivery that the team can explain, challenge, and maintain.
In this article
Last updated October 14, 2026
7 min read
AI coding creates a review bottleneck when generation increases faster than the team’s ability to verify intent, risk, tests, and maintainability. This question matters because faster generation moves work into decisions that still require evidence and ownership.
Software teams spent years trying to shorten the time between an idea and a first implementation.
Coding agents changed that part of the system quickly. A plausible first draft can now appear before a planning meeting would have ended. Several agents can work in parallel. Tests, documentation, and review summaries can arrive with the code.
The obvious conclusion is that delivery should become faster by the same amount.
That conclusion misses the queue.
When generation becomes abundant, the scarce work moves to deciding whether the generated change is the right change, whether its evidence is meaningful, and whether the team can safely own it.
The new queue begins after the answer
Stack Overflow’s 2025 Developer Survey gives this problem recognisable language. Among respondents who answered the AI frustration question, 66% selected solutions that were almost right, and 45% selected more time spent debugging AI-generated code.
These are self-reported survey responses. They do not prove that AI slows every team or that every generated change is wrong. They show why the first answer is a weak unit of productivity.
Almost-right code is expensive because it looks familiar. It follows local naming. It may pass a quick test. It can explain itself clearly. The reviewer must now detect the missing requirement, the unapproved assumption, the weak test, or the boundary that moved.
The code was cheap to produce. The proof did not become cheap automatically.
Why ordinary review stops scaling
Agents can reverse that relationship. One engineer can initiate several changes while the same small group of senior people still owns architecture, security, product consistency, and production risk.
The result is not simply “more code to review.” It is more decisions hidden inside code:
Where review work hides
- Which existing component should have been reused?
- Which interpretation of an unclear requirement became the implementation?
- Which dependency was selected and why?
- Which test was derived from the specification, and which merely mirrors the code?
- Which documentation became stale?
- Which finding is deterministic and which is model judgement?
If every reviewer starts from a diff and a confident summary, the queue will grow faster than the team can hire.
Redesign review around evidence
The answer is not to remove the human or require them to inspect every generated token.
The answer is to change what reaches the human.
Start with a stable target
Write observable behaviour, important invariants, and proof methods before implementation. A reviewer should be able to compare the change with an approved target instead of reconstructing the request from code.
Separate maker and checker
The agent that implemented the change already carries its assumptions. Give a separate reviewer the specification, diff, check results, and a clear job: find unproven promises, unwanted behaviour, and boundary violations.
Let scripts prove scriptable facts
Tests, types, lint, builds, schemas, package existence, file drift, and architecture rules can produce recorded results. A model can interpret them, but it should not invent whether they passed.
Route review by risk
A copy change should not wait behind an access-control change with the same workflow. Use a light path for small, reversible work and stronger specification, specialist review, and human decisions for sensitive changes.
Give the human a verdict packet
The final reviewer needs the promised behaviour, changed scope, deterministic results, judgement-based findings, open uncertainty, decisions already made, and rollback information. They do not need the full transcript.
Measure the whole path
Generated lines and opened pull requests show activity. They do not show whether the queue improved.
Measure:
- time to accepted change;
- review time per accepted change;
- correction turns before acceptance;
- escaped defects;
- requirements without evidence;
- unrequested changed behaviour;
- documentation drift;
- changes a reviewer returns as inconclusive;
- team understanding of the affected area.
This is how a team learns whether AI created useful capacity or only moved work into a less visible queue.
Trace one change through the bottleneck
Choose a recent change where review arrival rate was disputed, late, or missing. Start from the accepted request rather than the final diff. Write down what the team knew before implementation, which boundary governed the work, and who could stop it. Then follow the change through planning, generation, verification, review, and release.
At each handoff, ask four concrete questions:
Run this in order
- Where is review arrival rate recorded?
- Can a reviewer judge qualified reviewer capacity without asking the original operator?
- Which artefact proves evidence completeness?
- Who owns time to accepted change when the evidence conflicts?
Do not convert the exercise into a maturity score. The useful result is a short list of missing links. One may belong in repository guidance, another in CI, and another in the release decision. Repair the earliest missing link first because every later reviewer otherwise inherits the same ambiguity.
Run a second comparable change after the repair. If review becomes faster only because the same expert still explains the work orally, the process has not transferred. If another qualified person can reach the decision from the stored evidence, the change is becoming repeatable.
A usable review record for this decision should identify the accepted request, the exact revision being judged, the source of review arrival rate, and the owner responsible for time to accepted change. It should also preserve disagreement: a reviewer who finds weak qualified reviewer capacity or missing evidence completeness needs a visible way to return the work as incomplete. That record gives the next developer a reliable starting point and prevents a confident summary from becoming the only explanation of what happened.
Capacity planning needs a shared definition of “ready for review.” A generated pull request without a stable request, reproducible checks, or declared uncertainty has arrived in the queue physically but is not ready for a decision. Count those incomplete handoffs separately. This distinction shows whether the bottleneck comes from reviewer scarcity or from agents sending unfinished evidence downstream. The remedies differ: reviewer scarcity may require narrower work in progress, while weak handoffs require better specifications and automated evidence before a human is asked to judge the change.
For a related view of the delivery system, read how AI-generated code changes review and how a reviewable AI feature plan works.
Sources used
- Stack Overflow Developer Survey 2025, AI, self-reported survey data on trust and common frustrations.
- Addy Osmani, Agentic Code Review, current practitioner analysis of review as scarce work.
If your team is generating work faster than it can verify and own it, explore the AI Delivery Programme.
Frequently Asked Questions
How do AI coding tools create a code review bottleneck?
AI coding creates a review bottleneck when generation increases faster than the team’s ability to verify intent, risk, tests, and maintainability. Judge the practice on one real change and keep the supporting evidence beside the work.
How do you measure whether review capacity can keep up?
Track review arrival rate, qualified reviewer capacity, evidence completeness, and time to accepted change together. A single speed or output number cannot show whether the team can safely accept and maintain the result.
Why does faster code generation make review slower?
Generated changes can arrive faster than qualified reviewers can understand them. The queue grows because each change still needs evidence about intent, risk, tests, and maintainability before it can be accepted.
Which review work can be automated safely?
Automate deterministic checks such as formatting, static analysis, dependency policy, and repeatable tests. Keep judgement about product intent, architectural fit, sensitive behaviour, and unresolved uncertainty with the people who own those decisions.
When should a team limit the number of AI-generated pull requests?
Set a limit when unfinished reviews keep accumulating, evidence quality falls, or reviewers start approving work they cannot explain. The limit should follow verified review capacity rather than the number of changes an agent can produce.
What shows that a review bottleneck is improving?
Look for shorter time to an accepted change, fewer review restarts, stronger evidence at the first handoff, and less rework after merge. A smaller queue alone can hide rushed or rejected work.





